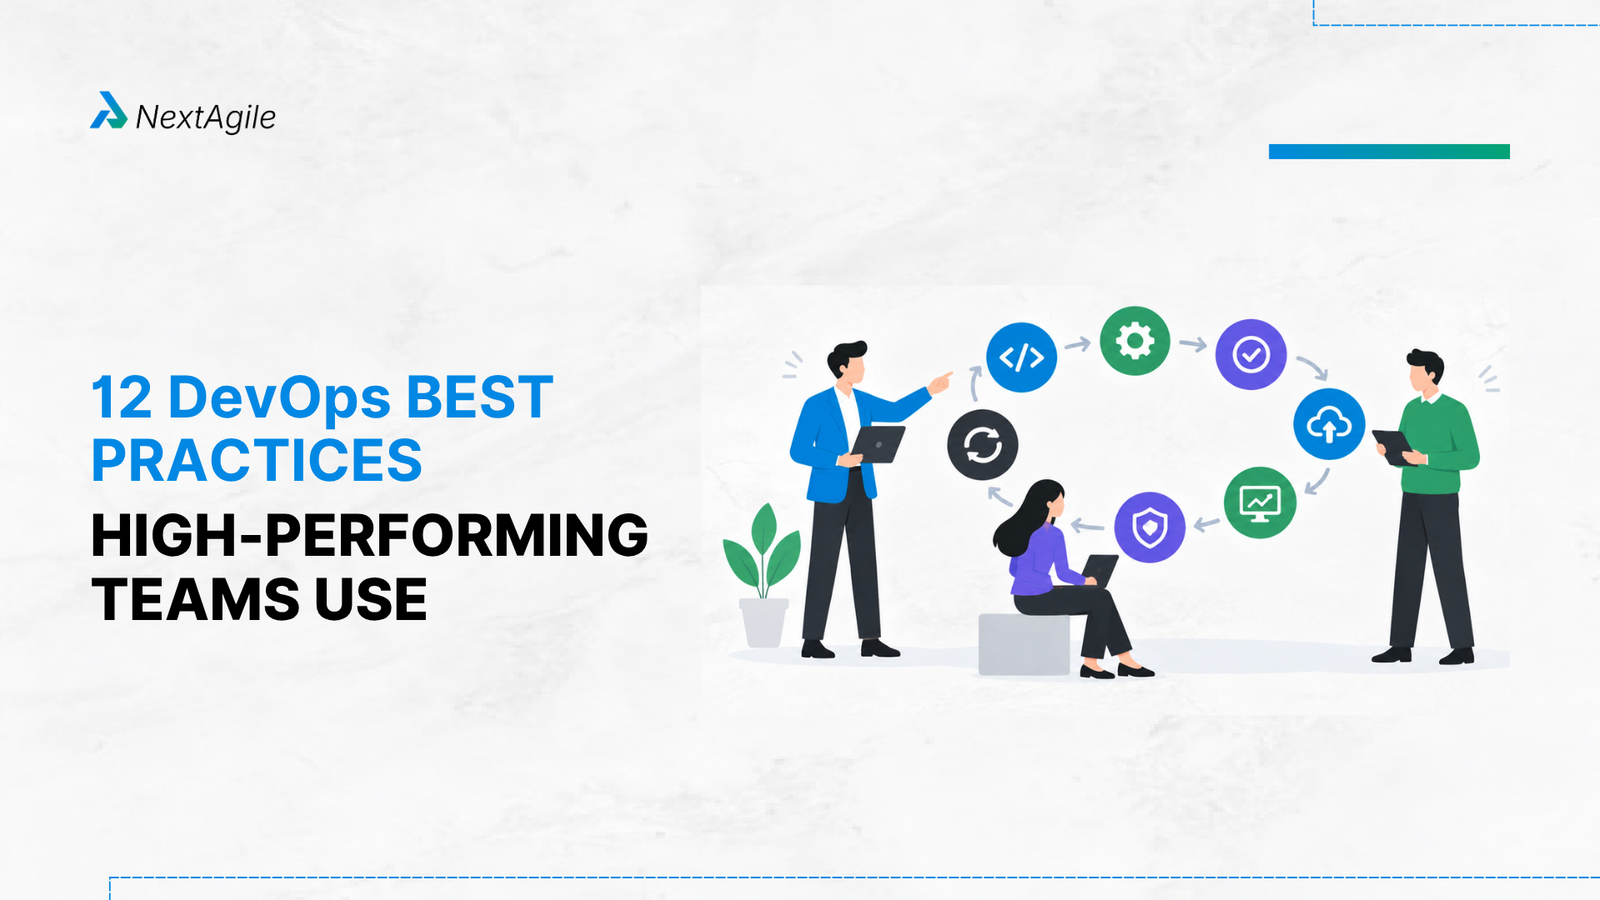
The most effective DevOps best practices in 2026 are not about adding more tools to the engineering stack. They are about improving the complete flow of software from development to production while keeping quality, security, reliability, cost, and customer value visible.
The core practices include continuous integration, continuous delivery, infrastructure as code, GitOps, automated testing, DevSecOps, observability, DORA metrics, internal developer platforms, FinOps, AI-assisted DevOps, and blameless continuous learning.
High performing teams do not adopt these practices as a checklist. They first identify where software delivery is getting stuck, then introduce the capability that removes that constraint.
Key Highlights of DevOps Best Practices DevOps in 2026 is moving from tool adoption toward end-to-end delivery system optimization. The objective is not simply to deploy more frequently but to deliver valuable changes safely, predictably, and with faster feedback.
The 12 practices covered in this guide are:
Continuous integration Continuous delivery and deployment Infrastructure as code GitOps Automated testing Shift left security and DevSecOps Observability DORA metrics Internal developer platforms and golden paths FinOps AI-assisted DevOps Blameless postmortems and continuous learning The most important starting point is to establish a delivery baseline, identify the biggest bottleneck, and improve that constraint before introducing additional automation.
AI makes this approach more important. Faster code generation can expose slow testing, manual approvals, unstable environments, weak security controls, and poor production visibility if the rest of the delivery system does not evolve.
A mature DevOps organization measures more than deployment frequency. It looks at delivery speed, stability, recovery, quality, engineering effort, infrastructure economics, and business outcomes together.
Introduction
DevOps has changed considerably since the early days of development and operations teams working to break down organizational silos. Today, it is increasingly connected to platform engineering, cloud infrastructure, cybersecurity, observability, FinOps, and AI-assisted software development.
That expansion has created a new challenge for technology leaders. There are now more DevOps tools, frameworks, platforms, and automation options than most organizations can realistically evaluate or implement.
Yet many organizations still experience slow releases, long testing queues, production incidents, manual approvals, infrastructure inconsistencies, and unpredictable delivery timelines.
The problem is often not a lack of technology. It is the way the technology, teams, processes, governance, and delivery workflows fit together.
That is why DevOps best practices in 2026 need to be viewed as capabilities within a delivery system rather than a collection of tools.
The real question is no longer which DevOps tool we should implement. The better question is where is value currently getting stuck, and what capability will remove that constraint?
What Are DevOps Practices and Why Do They Matter? DevOps practices are repeatable engineering, operational, security, measurement, and collaboration practices that improve the movement of software from idea to production and from production back to learning.
They connect development, testing, security, infrastructure, operations, product, and business teams around a common outcome. That outcome is the reliable delivery of valuable software.
A tool can enable a DevOps practice, but it cannot create the practice by itself. A CI platform does not create continuous integration. A cloud platform does not create infrastructure as code. A monitoring product does not create observability.
The practice exists in the way people work, make decisions, automate activities, measure outcomes, and respond to feedback.
What Changed in DevOps by 2026? Earlier DevOps programs often concentrated on automating builds and deployments. Those capabilities remain essential, but the scope has expanded as software systems and engineering organizations have become more complex.
The focus has moved from isolated automation toward the entire software delivery system. Platform engineering, GitOps, observability, security automation, FinOps, and AI are now increasingly connected to the way teams build and operate software.
This creates a broader definition of DevOps maturity.
A mature organization does not simply ask whether deployment is automated. It asks whether a validated change can move from developer intent to customer value with minimal waiting, predictable controls, visible risk, and rapid feedback.
Culture First vs Tools First DevOps A tool’s first transformation usually starts with technology selection. Teams choose a CI platform, migrate repositories, introduce Kubernetes, purchase observability software, or implement a new security scanner.
These investments can be useful, but technology does not automatically solve delivery constraints. If three teams still wait for manual approval before every release, a sophisticated deployment platform will not eliminate that queue.
A culture-first approach begins with the delivery system. Teams examine where work waits, where defects appear, where handoffs occur, where decisions are delayed, and where manual intervention creates unnecessary friction.
The technology is then selected to support the improved operating practice.
The AI Productivity Paradox in DevOps AI can increase the speed at which developers generate code, tests, documentation, infrastructure configurations, and technical analysis. But faster code creation does not automatically mean faster software delivery.
If developers produce changes faster than the test pipeline can validate them, testing becomes the constraint. If deployment remains manual, the release queue becomes the constraint. If production telemetry is weak, faster releases can increase uncertainty.
AI can increase engineering capacity while exposing weaknesses elsewhere in the delivery system.
That is why AI-assisted delivery makes DevOps fundamentals more important, not less. The organizations that benefit most will be those that improve the complete delivery system around faster engineering.
Start With a Baseline Before Adding Practices Before implementing another DevOps capability, establish a baseline for the current delivery system.
Measure deployment frequency, change lead time, change failure rate, and recovery time. For a practical walkthrough of how to apply them, see our guide to DORA metrics for DevOps.
The purpose of the baseline is not to create another reporting exercise. It is to understand where improvement will create the greatest business impact.
High performing teams do not optimize every part of the system at once. They identify the constraint, improve it, measure the result, and then move to the next constraint.
The Core DevOps Principles Behind These Practices The individual practices in this guide are built around a small set of underlying DevOps principles.
The first is flow. Work should move through development, testing, security, deployment, and operations without unnecessary queues or handoffs. The second is feedback. Teams need fast information about quality, security, reliability, customer behavior, and delivery performance.
The third is automation. Repetitive work should be automated where automation improves speed, consistency, and control. The fourth is shared ownership. Teams should understand how their changes affect customers and production rather than treating operations as somebody else’s responsibility.
The fifth is continuous improvement. DevOps maturity is not a destination. Teams continuously examine the delivery system and improve the constraints that prevent better outcomes.
These principles also explain why DevOps culture matters. A team can implement every major DevOps technology and still struggle if people work in isolated functions, hide failures, optimize local metrics, or treat production feedback as an operations problem.
12 DevOps Practices and Capabilities High Performing Teams Use 1. Continuous Integration Continuous integration means frequently integrating code into a shared repository and automatically validating changes through builds, tests, quality checks, and other controls.
The purpose is to reduce the risk associated with large batches of unintegrated work. Smaller changes create smaller problems when something fails and make the source of the failure easier to identify.
A common failure is creating a CI pipeline that frequently remains broken. Teams then learn to ignore failures because the pipeline is no longer trusted.
The practical starting point is simple. Establish a reliable build and validation pipeline for one product or service and keep the main branch in a usable state.
Track build success rate, build duration, and the time between code commit and validated change.
2. Continuous Delivery and Deployment Continuous delivery keeps software in a releasable state through automated build, testing, packaging, and deployment processes. Continuous deployment takes this further by automatically moving validated changes into production.
The distinction matters because continuous delivery does not mean every change must automatically reach customers. It means the organization has the technical capability to release when the business is ready.
A common failure occurs when teams automate deployment but retain manual environment configuration, approval queues, or release procedures.
Start by automating deployment into a controlled environment. Then progressively introduce production automation using appropriate release strategies and controls.
Track change lead time and deployment frequency, but always consider them alongside stability and quality.
3. Infrastructure as Code Infrastructure as code manages infrastructure through version controlled definitions rather than manual configuration.
Networks, compute resources, databases, permissions, environments, and other infrastructure components can be defined, reviewed, tested, and provisioned through code.
The major benefit is consistency. When environments are created through repeatable definitions, teams reduce configuration drift and make infrastructure changes easier to audit and reproduce.
The common failure is allowing emergency manual changes to become permanent exceptions. Over time, the actual environment no longer matches the declared configuration.
Start with one repeatable environment and bring its infrastructure under version control.
Track the percentage of infrastructure managed through approved, version controlled definitions.
4. GitOps GitOps applies declarative, version controlled configuration and continuous reconciliation to infrastructure and application operations.
Instead of relying on engineers to manually change a running environment, teams define the desired state in Git and use automated mechanisms to keep the actual environment aligned with that state.
This creates stronger traceability for operational changes and can simplify rollback, auditing, and environment consistency. GitOps is most often applied in Kubernetes environments, so a working grasp of Kubernetes orchestration makes the pattern much easier to adopt.
The common mistake is treating GitOps as simply storing YAML files in a repository. GitOps is more than version control.GitOps is more than version control. The OpenGitOps principles describe it as depending on a declarative desired state, versioned and immutable storage, automatic application of changes, and continuous reconciliation.
Start with one application or environment and make Git the authoritative source for its operational configuration.
Track the percentage of operational changes that follow the approved GitOps workflow.
5. Automated Testing at Every Stage Automated testing provides rapid feedback throughout the delivery lifecycle rather than concentrating validation at the end of development.
A balanced strategy can include unit, integration, API, contract, security, regression, performance, and end-to-end testing. The goal is not to automate everything. The goal is to place reliable tests at the right points in the delivery flow.
This becomes especially important when AI-assisted development increases the rate of code creation.
One common mistake is building enormous end-to-end suites that take hours to execute and frequently fail for reasons unrelated to actual product defects.
Start by identifying which tests provide the fastest and most reliable feedback. Move those tests closer to code integration and continuously improve their reliability.
Track test execution time, pass rate, flaky test rate, and defect escape.
“For teams strengthening this capability, an Agile test automation framework provides a useful foundation for integrating automation with Agile delivery.
6. Shift Left Security and DevSecOps DevSecOps integrates security into software development and operations rather than positioning security as a final release gate.
The practice can include secure coding, dependency scanning, secret detection, static analysis, dynamic testing, container security, infrastructure security, software supply chain controls, and vulnerability management.
The objective is not to create more security gates. It is to identify security issues earlier while giving developers useful feedback during the normal delivery workflow.
A common failure occurs when security controls create so much friction that developers begin treating them as obstacles rather than engineering safeguards.
Start with automated dependency scanning, secret detection, and appropriate security checks in the CI pipeline.
Track time from vulnerability detection to remediation and monitor recurring classes of security issues.
7. Observability, Not Just Monitoring Monitoring primarily helps answer whether a system is functioning. Observability helps teams understand what is happening inside the system and why.
Modern observability can combine metrics, logs, traces, events, service level indicators, application signals, and business telemetry.
This matters because distributed systems can fail in ways that are difficult to understand from a single dashboard. A customer issue may involve several services, infrastructure layers, external dependencies, and a recent deployment.
The common failure is collecting enormous amounts of telemetry without deciding which signals actually matter.
Start with one critical service and define the signals that indicate availability, performance, reliability, and customer impact.
Track time to detect, time to diagnose, and time to recover from significant incidents.
8. DORA Metrics as a Performance Baseline DORA metrics provide a structured way to understand software delivery performance. DORA’s four key metrics give the most widely used baseline, which teams can extend with measures such as deployment rework.
These metrics are valuable because they move the conversation away from activity measures such as ticket counts, story points, or lines of code.
The important principle is to use DORA metrics as signals for system improvement rather than as individual performance scores. When teams are pressured to optimize a single number, the metric can become the target instead of the outcome.
Start with a baseline for one product or service and examine the metrics together.
For organizations connecting engineering performance with business objectives, DevOps OKRs can help translate delivery improvements into measurable outcomes.
9. Internal Developer Platforms and Golden Paths As technology ecosystems become more complex, developers can spend significant time dealing with infrastructure, security, deployment configuration, environments, and operational processes.
Internal developer platforms reduce this cognitive load by providing reusable capabilities and supported workflows.
A golden path gives developers a recommended way to perform common activities such as creating a service, configuring CI, enabling security checks, setting up observability, and deploying an application.
The common failure is building a platform that developers are required to use but do not find useful.
Start by identifying the most repeated engineering workflows and make those workflows easier through templates, automation, and self-service capabilities.
Track developer onboarding time, platform adoption, and time spent on common engineering setup activities.
10. FinOps Integration Cloud delivery has changed the relationship between engineering decisions and technology costs. Infrastructure consumption can increase or decrease based on architecture, traffic, deployment patterns, environments, and application behavior.
FinOps brings engineering, finance, product, and business stakeholders into a shared conversation about technology consumption and value.
For DevOps teams, this means making infrastructure economics visible at the product or service level rather than reviewing cloud spend only as a monthly finance report.
The common failure is discovering excessive consumption after engineering decisions have already been made.
Start by assigning meaningful cost visibility to products or services and include engineering owners in regular cost reviews.
Track cost per customer, transaction, product, workload, or another unit that reflects business value.
11. AI-Assisted DevOps AI-assisted DevOps can support code generation, test creation, code review, incident analysis, log interpretation, documentation, infrastructure recommendations, vulnerability analysis, and operational knowledge retrieval.
The opportunity is significant, but the implementation needs discipline.
AI should remove repetitive cognitive work while preserving appropriate engineering review, testing, security, and operational controls.
The common mistake is measuring AI adoption through generated code or the number of developers using an AI assistant. Those measures show activity, not business value.
Start with one high-volume, low-risk workflow and measure the actual effect on engineering time, quality, delivery speed, or incident response.
Track change lead time, review cycle time, defect rate, and measurable engineering effort saved.
Organizations exploring the broader intersection of AI and Agile can also explore AI in Agile ..
12. Blameless Postmortems and Continuous Learning High performing DevOps organizations understand that complex software systems will eventually fail. The difference is how quickly the organization detects the problem, restores service, understands what happened, and prevents recurrence.
A blameless postmortem examines system conditions, contributing factors, detection mechanisms, decisions, recovery actions, and improvement opportunities.
The objective is not to determine who made the mistake. Google’s SRE guidance on postmortem culture explains why blameless reviews help teams surface real contributing factors instead of encouraging people to hide them.
The common failure is conducting a postmortem and then allowing its corrective actions to disappear into a backlog.
Teams that already run sprint retrospectives can reuse that habit of assigning owners and deadlines to a small number of meaningful improvements.
Track corrective action completion and recurrence of similar incidents.
How to Choose Which DevOps Practice to Start With The 12 practices should not become another transformation checklist.
If a team attempts to implement CI, GitOps, Kubernetes, platform engineering, DevSecOps, FinOps, observability, and AI simultaneously, the transformation itself can become a source of complexity.
The better approach is to identify the biggest constraint in the current delivery system.
Find the Biggest Bottleneck in Your Delivery Flow Map the movement of work from development through integration, testing, security, release, deployment, production, and customer feedback.
Look specifically for waiting time.
A team may discover that development takes two days, testing takes one day, but work waits three days for a shared environment and another two days for manual security approval.
In that situation, writing more code faster will not solve the delivery problem.
This is where value stream mapping becomes useful. Value stream mapping consulting can help organizations visualize queues, handoffs, rework, dependencies, and delays across the delivery system.
Match the Bottleneck to the Right DevOps Practice A team experiencing frequent integration conflicts may need stronger continuous integration. A team with long manual releases may need continuous delivery. A team struggling with inconsistent environments may need infrastructure as code. A Kubernetes environment suffering configuration drift may benefit from GitOps. A team finding defects late may need better automated testing. An organization experiencing slow incident diagnosis may need observability. A company struggling to understand delivery performance may need a DORA baseline. The practice should follow the problem rather than the other way around.
How to Sequence DevOps Improvements Without Over Automating A practical sequence starts with visibility.
First understand the current flow. Then stabilize broken processes, automate repeatable work, improve feedback, standardize common workflows, and optimize cost.
Only after the foundation is stable should organizations aggressively expand AI assisted engineering or more advanced automation.
This sequence prevents a common transformation mistake: using automation to make a poorly designed process faster without addressing why the process is inefficient.
A Practical DevOps Maturity Model for 2026 DevOps maturity can be viewed as a progression rather than a binary state.
At the reactive stage, teams rely heavily on manual deployment, siloed ownership, limited automation, and reactive incident management.
At the automated stage, teams establish CI/CD, automated testing, infrastructure as code, and repeatable deployment processes.
At the measured stage, teams introduce DORA metrics, observability, reliability practices, and delivery performance baselines.
At the platformized stage, internal developer platforms, golden paths, GitOps, and self-service capabilities reduce repeated engineering effort.
At the intelligent stage, AI-assisted engineering, FinOps, predictive insights, and continuous optimization become integrated into the delivery system.
The important point is that maturity is not measured by how many technologies an organization has implemented.
It is measured by how reliably the organization can move valuable change through the system while maintaining quality, security, reliability, and economic control.
DevOps Practices in Agile and Scaled Delivery DevOps and Agile solve different parts of the same delivery challenge.
Agile provides principles and practices for iterative development, prioritization, collaboration, customer feedback, and adaptation. DevOps extends that flow into integration, testing, security, infrastructure, deployment, operations, and production feedback.
A strong Agile team should therefore be able to move from a prioritized backlog to validated, deployable software without creating a large queue between development and production.
How DevOps Practices Fit Into Agile and Scrum DevOps practices can operate throughout the Sprint.
A developer commits a change, the CI pipeline validates it, automated tests provide feedback, security checks run, the application is packaged, and the team can deploy it through an appropriate release process.
This creates a shorter feedback loop between development decisions and actual product behavior.
It also changes the meaning of Done. For a mature team, Done should increasingly reflect software that has been properly tested, secured, documented, observable, and capable of being released.
Teams strengthening their Agile foundation can explore the Agile and Scrum Masterclass .
DevOps and Continuous Delivery in SAFe In scaled delivery environments, DevOps becomes increasingly important because value often crosses several teams, platforms, and organizational boundaries.
A single team may complete development quickly while waiting for another team for testing, infrastructure, security, integration, or release management.
DevOps practices help expose and reduce those queues.
The goal in a scaled environment should therefore not be to make each team independently faster. It should be to improve the end-to-end flow of value across the entire value stream.
Use Value Stream Mapping Before Adding DevOps Practices Value stream mapping can reveal where delivery time is actually being consumed.
Consider a hypothetical enterprise workflow where development takes two days, testing takes one day, security validation takes one day, and deployment takes two hours, but the work waits several days between each stage.
The deployment technology is not necessarily the constraint.
The queues are.
This distinction matters because the organization may otherwise invest in faster deployment technology while leaving the larger system unchanged.
For enterprise teams, software delivery management provides another useful lens for connecting engineering execution with predictable delivery outcomes.
What DevOps Practices Mean for Enterprise Teams Enterprise DevOps introduces additional complexity because teams rarely operate in isolation.
There may be regulatory requirements, legacy systems, multiple cloud environments, shared platforms, architecture dependencies, centralized security functions, release governance, and different technology stacks.
The solution is not to remove every control.
The goal is to make controls part of the delivery flow so that compliance, security, quality, and operational requirements can be addressed without creating unnecessary queues.
For example, a regulated financial services organization may require security validation and auditability before production deployment. DevSecOps, infrastructure as code, automated evidence collection, and controlled deployment workflows can make those requirements part of the pipeline rather than separate manual activities.
That is where enterprise DevOps becomes more than an engineering initiative. It becomes an operating model for how technology moves from idea to customer value.
Common Mistakes When Adopting DevOps Practices Tooling Before Operating Practices A new platform cannot compensate for unclear ownership, broken workflows, or unnecessary approval queues.
Define the operating problem before selecting the technology.
Automating the Wrong Bottleneck Automation is not automatically an improvement.
If testing is not the constraint, adding another testing tool will not necessarily improve delivery. If deployment is already fast, investing heavily in deployment automation may produce little additional value.
Automate the constraint first.
Measuring Activity Instead of Outcomes Number of deployments, commits, tickets, story points, or AI-generated code can provide context.
They should not become substitutes for delivery outcomes.
Measure speed, stability, recovery, quality, cost, and customer impact.
Skipping DORA Baselines Without a baseline, teams can confuse activity with improvement.
Measure the current state before launching major DevOps initiatives and compare performance over time.
Treating DevOps as a Team Rather Than an Organizational Capability Creating a DevOps team does not automatically create DevOps.
If developers, testers, security, infrastructure, and operations still operate through separate queues and handoffs, the underlying delivery system remains fragmented.
DevOps is ultimately about how the organization delivers software, not the name of a department.
A 2026 DevOps Diagnostic for Technology Leaders Before investing in another DevOps platform, technology leaders should be able to answer five questions.
How long does a validated change take to reach production? Where does software spend the most time waiting? How much testing, security validation, and deployment work still requires manual intervention? How quickly can the organization detect, diagnose, and recover from production failure? Can engineering leaders connect delivery performance and technology costs to customer or business outcomes? If the answers are unclear, the organization may need better visibility before it needs another tool.
This diagnostic also creates a useful starting point for an enterprise transformation roadmap. It helps leaders move from broad DevOps ambitions to a focused improvement agenda.
Conclusion The most important shift in DevOps best practices in 2026 is the move from tool adoption to delivery system optimization.
High performing teams are not necessarily the teams with the largest automation stack. They are the teams that can identify where value is getting stuck, remove the constraint, and establish a measurable feedback loop around the entire delivery system.
Continuous integration, continuous delivery, infrastructure as code, GitOps, automated testing, DevSecOps, observability, DORA metrics, developer platforms, FinOps, AI-assisted engineering, and continuous learning all contribute to that system.
But they should not be implemented simply because they appear on a DevOps maturity checklist.
The better approach is diagnostic. Understand the current flow, establish a baseline, identify the constraint, improve it, measure the result, and then address the next constraint.
That is the difference between implementing DevOps practices and building a high performing software delivery organization.
For enterprises looking to connect DevOps improvements with broader business agility, Agile transformation consulting can help align delivery practices, operating models, technology capabilities, and measurable business outcomes.
If your teams struggle with slow releases, delivery bottlenecks, manual processes, or recurring production issues, a structured DevOps approach can help. NextAgile consulting can help you identify delivery constraints and co-create a practical DevOps and Business Agility roadmap. Reach out to us at consult@nextagile.ai and we would be happy to explore more.
Frequently Asked Questions 1. Which DevOps practice should a team implement first? Start with the biggest constraint in the software delivery flow. For some teams, that may be continuous integration or automated testing. For others, it may be deployment automation, infrastructure as code, security automation, or observability.
The right starting point depends on the organization’s current delivery baseline rather than a fixed implementation sequence.
2. How do DevOps practices differ from Agile practices? Agile focuses on iterative product development, collaboration, prioritization, customer feedback, and responding to change.
DevOps extends those principles into integration, testing, security, infrastructure, deployment, operations, monitoring, and production feedback.
They are complementary approaches that work together to improve the flow from customer need to working software.
3. What are DORA metrics and why do they matter? DORA metrics provide a way to understand software delivery performance through measures such as change lead time, deployment frequency, change failure rate, failed deployment recovery time, and deployment rework.
They help teams establish a baseline and identify whether delivery changes are improving speed and stability.
4. How long does it take to see results from DevOps adoption? The timeline depends on the organization’s starting maturity, architecture, technology environment, team structure, dependencies, and transformation scope.
Some improvements, such as automating a repetitive deployment workflow, can show results quickly. Broader enterprise changes involving operating models, platforms, culture, governance, and skills require sustained improvement.
The most reliable approach is to measure the baseline, target a specific constraint, and track the result.
5. What is DevSecOps and how is it different from DevOps? DevSecOps integrates security into the DevOps lifecycle.
Instead of treating security as a final stage before production, teams incorporate security practices into development, CI/CD, infrastructure, deployment, and operations.
The objective is earlier detection, faster remediation, and stronger security without creating unnecessary delivery bottlenecks.
6. Can small teams implement DevOps practices? Yes. Small teams can begin with version control, continuous integration, automated testing, CI/CD, infrastructure as code, basic observability, security scanning, and delivery metrics.
They do not need a large enterprise platform to begin.
The practices can mature as the product, infrastructure, customer base, and engineering organization grow.
Anuj Ojha is Co-Founder & Consulting Head at NextAgile. Anuj has designed & led multiple turnkey transformation journeys across industries, domains & geographies and has 16+ years of experience as an agile practitioner. He has worked with CXOs, CTOs & Key Leaders to translate their business objectives on the ground, contextualizing org transformations and creating buy-in across level, leading a team of coaches/consultants to implement agility across 150+ teams & trained more than 12k team members. Anuj’s core area of interest is business agility & working with leaders & teams to achieve long term sustainable, Agile culture & mindset.
 Skip to content